
GPU servers
Your own GPUs.
No waiting room.
NVIDIA RTX PRO 4000 and 6000 Blackwell, from one card to four cards with 384 GB VRAM in one machine. For AI inference, fine-tuning, rendering and video, per month, in the EU, with no egress costs.

NVIDIA RTX PRO 6000 Blackwell.
96 GB per card.
The fastest professional GPU of the moment, in our dedicated servers (Max-Q, one to four cards) and in enterprise projects as Server Edition with up to eight cards per system. Our own hardware in the EU, per month, with no egress costs.
- 96 GBGDDR7 ECC per card
- 5th genTensor cores · FP4
- 4th genRT cores
- 1 to 8cards per system
Hardware from
Run your own models (Llama, Mistral, Whisper, Stable Diffusion) without paying per token. 24 GB VRAM is enough for 7B to 13B models. 96 GB is enough for 70B in 4-bit.
LoRA and QLoRA on your own data, with your data kept in the EU. Four cards with NVLink-like bandwidth for larger runs.
Blender, Unreal, DaVinci, transcoding: RT cores and NVENC, all night long, without blocking your workstation.
ECC memory for calculations you can trust. Add a remote desktop and your team can work from any laptop.
Four GPUs. 384 GB VRAM. One machine.
Four NVIDIA RTX PRO 6000 Blackwell Max-Q in one dedicated server: run several language models side by side (customer service, coding help, document processing), or one large model for hundreds of concurrent users. Open-weight models like GLM, Mistral and Qwen on your own hardware in the EU: your documents, customer data and source code stay within your own environment.
Order GEX430 · € 5,413.95 per month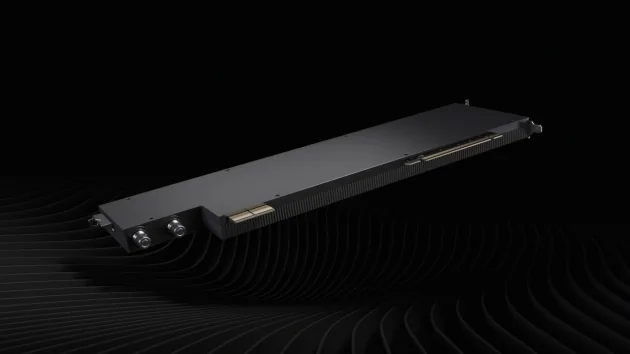
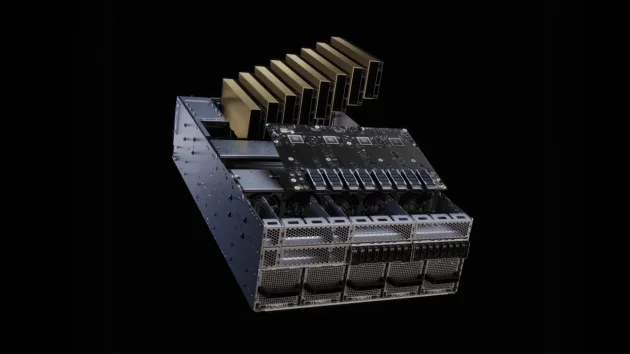
Up to eight Server Edition GPUs per system, as your own cluster.
For inference at scale, training or building your own AI factory, we build a custom environment: systems with up to eight RTX PRO 6000 Blackwell Server Edition cards, fast network cards, storage and the software around it (Kubernetes, vLLM, monitoring). From € 100,000 one-time and € 10,000 per month, management included.
Enterprise infrastructureThe GPU servers
Dedicated, with the full card for you alone. Ubuntu with NVIDIA drivers and CUDA ready to go, managed for you.
 GEX45-1AI, rendering, videoon request Intel Core i5-13500 14 Corecores14 cores ram64 GB DDR4 storage2 x 512 GB NVMe RTX 4000 SFF Blackwell Generation € 336.95root · managed € 410.95setup € 250.95 one-time Order
GEX63-1AI, rendering, videoon request Intel Core Ultra 7 265 20-Corecores20 cores ram128 GB DDR5 storage2 x 1.92 TB NVMe RTX PRO 6000 Blackwell Max-Q € 1,513.95root · managed € 1,587.95setup € 1,198.95 one-time Order
GEX131-1AI, rendering, videoon request Intel Xeon Gold 5412U 24-Corecores24 cores ram256 GB DDR5 ECC reg. storage2 x 960 GB NVMe RTX PRO 6000 Blackwell Max-Q € 2,263.95root · managed € 2,337.95setup € 1,798.95 one-time Order
GEX131-2AI, rendering, videoon request Intel Xeon Gold 5412U 24-Corecores24 cores ram512 GB DDR5 ECC reg. storage2 x 1.92 TB NVMe RTX PRO 6000 Blackwell Max-Q € 3,163.95root · managed € 3,237.95setup € 2,518.95 one-time Order
GEX131-3AI, rendering, videoon request Intel Xeon Gold 5412U 24-Corecores24 cores ram768 GB DDR5 ECC reg. storage4 x 3.84 TB NVMe RTX PRO 6000 Blackwell Max-Q € 4,063.95root · managed € 4,137.95setup € 3,238.95 one-time Order
GEX430-1AI, rendering, videoon request Intel Xeon Gold 5412U 24-Corecores24 cores ram128 GB DDR5 ECC reg. storage2 x 1.92 TB NVMe 4x RTX PRO 6000 Blackwell Max-Q € 5,413.95root · managed € 5,487.95setup € 4,318.95 one-time Order
Frequently asked questions
Are the drivers already installed?
With managed, we set up Ubuntu with the NVIDIA driver, CUDA and Docker with the NVIDIA runtime. You can start a container right away. With root, you do it yourself (nvidia-driver via apt takes ten minutes).
Can I pay per hour?
We invoice per month, and you can cancel monthly. For a few hours of computing, a cloud GPU is cheaper. For anything that runs longer than a week, your own card is many times cheaper.
Which card for which model?
RTX PRO 4000 (24 GB): models up to ±13B, Whisper, image generation. RTX PRO 6000 (96 GB): 70B in 4-bit, larger batch inference, fine-tuning. Four times 6000: training and multi-GPU inference.
Where are the servers?
In Helsinki or Falkenstein, within the EU. Your data does not leave Europe.
Can you set up the model for me?
Yes, as interim or project work: from vLLM and Ollama to your own API with rate limiting. Send us a message with what you want to run.
Not sure about the card?
Tell us what you want to run. We will work out which GPU and how much VRAM you need.
